Data to train your AI.
AI Model Datasets
In simple words: We collect and label large amounts of clean data so your team can train and test AI models without spending months gathering it.
High-quality datasets for training machine learning models and LLMs: collected from public sources or generated synthetically, cleaned and exported in ML-ready formats.
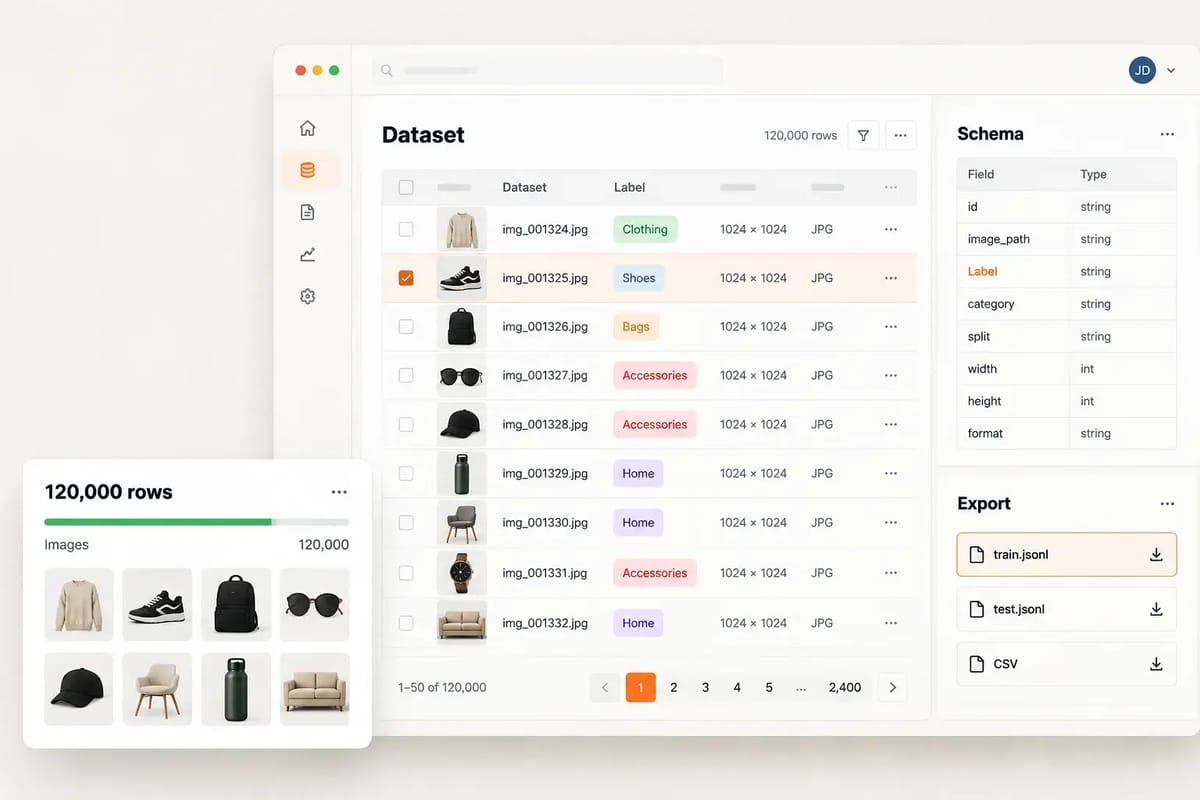
For example: An AI startup needed a large, labelled product dataset to train a category classifier. The team started training within days instead of months. See how we did it ↓
The problem
Why teams come to us
The quality of your AI model depends on the quality of your training data, and messy scrape dumps or tiny samples are not enough.
What you get
- Custom dataset creation to your schema and volume
- Public web collection and/or synthetic data
- Data annotation and labelling workflows
- Dataset validation, deduplication and a data dictionary
- CSV, JSON, Excel or JSONL for LLM fine-tuning
- Free sample rows before the full build; regular updates on request
Benefits
What changes for your team
Get high-quality, relevant training data
Save months of data collection effort
Improve model accuracy with clean data
Scale dataset size as your needs grow
Receive data in ML-ready formats
How it works
From first call to working result
- 1
Discovery call
A free 30-minute call to map your goal, sources, volume and where the result should land. NDA on request.
- 2
Sample first
We build a small working sample so you can check fields, format and quality before the full build.
- 3
Build & test
We build the full solution, test it on real data and edge cases, and share progress as we go.
- 4
Deliver & support
You get the result, the source code and short handover notes, plus fixes during the support window.
Example project
A product dataset for a classifier
- The challenge
- An AI startup needed a large, labelled product dataset to train a category classifier.
- What we built
- We collected public product data, normalised the fields, labelled categories and exported train and test splits.
- The outcome
- The team started training within days instead of months.
An illustrative example of a typical AI training datasets engagement.
Use cases
Where this helps
Tech stack
Tools we use
FAQ
Questions about AI training datasets
Can I see a sample first?
Yes, we deliver sample rows so you can approve the schema before the full build.
Do you collect personal data?
No. We use public, non-personal data or privacy-safe synthetic data.
Which formats do you deliver?
CSV, JSON, Excel, Parquet or JSONL ready for OpenAI, Hugging Face and Llama-style fine-tuning.
Related services
Often combined with
Ready to talk about AI training datasets?
Send a short brief or book a call. A senior engineer replies within a few hours.